Google released EmbeddingGemma 2 which they claim is the most capable open source model for multi-model embeddings. In addition to text, it can handle similarity across images, audio and video. I wanted to do an evaluation on its claims and I had the perfect candidate. Replacing the embeddings engine in my iOS news app which relies on iOS NLContextualEmbeddings.
The engine swap was mostly seamless. Well, other than one hiccup, which was that my app now had to download a 300MB file (the new model) upon launch. Apple ships its models on device, so using their built-in libraries you get this for free.
Apple thankfully provides a mechanism to upload and seed large files through the App Store’s transporter app. It works like how big games get downloaded. You have a small App Store package, then by requesting an App Group entitlement, you can download a secondary package, in my case Google’s EmbeddingGemma 2 text only model.
I asked Claude to use CoreML because the model could fall back to the built-in iOS Foundation models without breaking. We found that FluidInference converted EmbeddingGemma 2 to CoreML and uploaded it on Huggingface. Excellent. I used this as a drop-in replacement.
After loading the EG2 model, I performed an eval of my interest matching for NL vs EG2. Only then did I realize how poorly my NL implementation performed.
| Metric | NLContextualEmbeddings | EmbeddingGemma 2 |
|---|---|---|
| Stories with a named reason | 65 / 901 | 297 / 901 |
| Top 25 of Today that clearly match you | 8 | 21 |
| Median age of the top 25 | 1.2 h | 1.7 h |
| Stories qualifying for For You | 26 | 96 |
| For You picks matching an interest you typed | 0 / 10 | 5 / 10 |
| Hero picks the two models share | 1 / 10 | 1 /10 |
| Same-event pairs grouped (120 pairs labelled by hand) | 12 / 23 | 18 / 23 |
| Wrong groupings | 16 | 2 |
| Followed-story matches accepted | 7 / 23 | 13 / 23 |
Another eval that I ran was to compare how much influence the “freshness” of the articles carried in surfacing that story in the top news feed. You can see how in the before graph, using NLContextualEmbeddings, the positions of an article in the today feed were mostly linear with time. As articles became older, they went further down the feed list. What this means, is that the “interest” surfacing that I had built with NL, did a lot of nothing. Whereas, with EmbeddingGemma 2, even if an article was old, they were still surfaced higher in the feed, if interests drove the story to higher relevance.
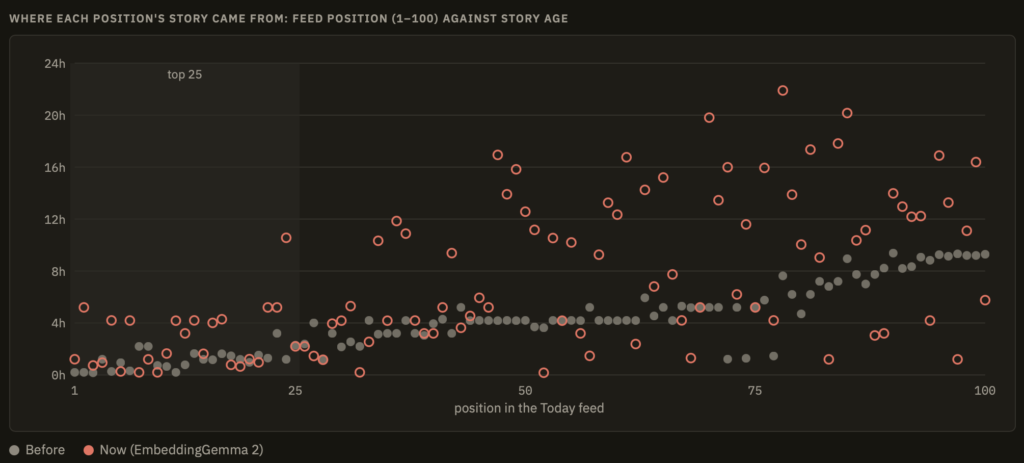
Was it worth it? Yes and I’m happy with the results. In using the news app I’m noticing not only are the built-in interests matching improved, but learned interests are robust too, reinforcing the matching engine. It’s not trivial to have a side-loaded 300MB model to download, but given the improvement to matching, it improves the user experience.
